
SUPERCOMPUTING NEWS SUPERCOMPUTING NEWS
    • MEDIA KIT
    • MOST READ
    • RSS FEED
    • ACADEMIA
    • AEROSPACE
    • APPLICATIONS
    • ASTRONOMY
    • AUTOMOTIVE
    • BIG DATA
    • BIOLOGY
    • CHEMISTRY
    • CLIENTS
    • CLOUD
    • DEFENSE
    • DEVELOPER TOOLS
    • EARTH SCIENCES
    • ECONOMICS
    • ENGINEERING
    • ENTERTAINMENT
    • GAMING
    • GOVERNMENT
    • HEALTH
    • OIL & GAS
    • INDUSTRY
    • INTERCONNECTS
    • MANUFACTURING
    • MIDDLEWARE
    • MOVIES
    • NETWORKS
    • PHYSICS
    • PROCESSORS
    • RETAIL
    • SCIENCE
    • STORAGE
    • SYSTEMS
    • VISUALIZATION
    • AcyMailing subscription form

    • ADD YOUR VIDEOS
    • MANAGE VIDEOS
    • CONVERSATION INBOX
    • SOCIAL ADVERTISER
    • SOCIAL NETWORK VIDEOS
    • SURVEYS
    • GROUPS
    • PAGES
    • MARKETPLACE LISTINGS
    • APPLICATIONS BROWSER
    • PRIVACY CONFIRM REQUEST
    • PRIVACY CREATE REQUEST
    • LEADERBOARD
    • POINTS LISTING
      • BADGES
    • TRADE SHOWS
Sign In
NVIDIA wants AI factories online in 14 days, but the infrastructure bottlenecks haven’t disappeared
Amazon’s €16 billion Germany pledge has a €4.8 billion AI question: Where is the new compute?
The $90 billion AI compute gamble: Nscale’s Anthropic expansion raises questions about delivery
NVIDIA’s Nordic AI supercomputer is real. Its gigawatt ambition is another matter.
The AI supercomputer’s power problem is moving inside the rack: Delta pushes 800 VDC toward NVIDIA’s next generation
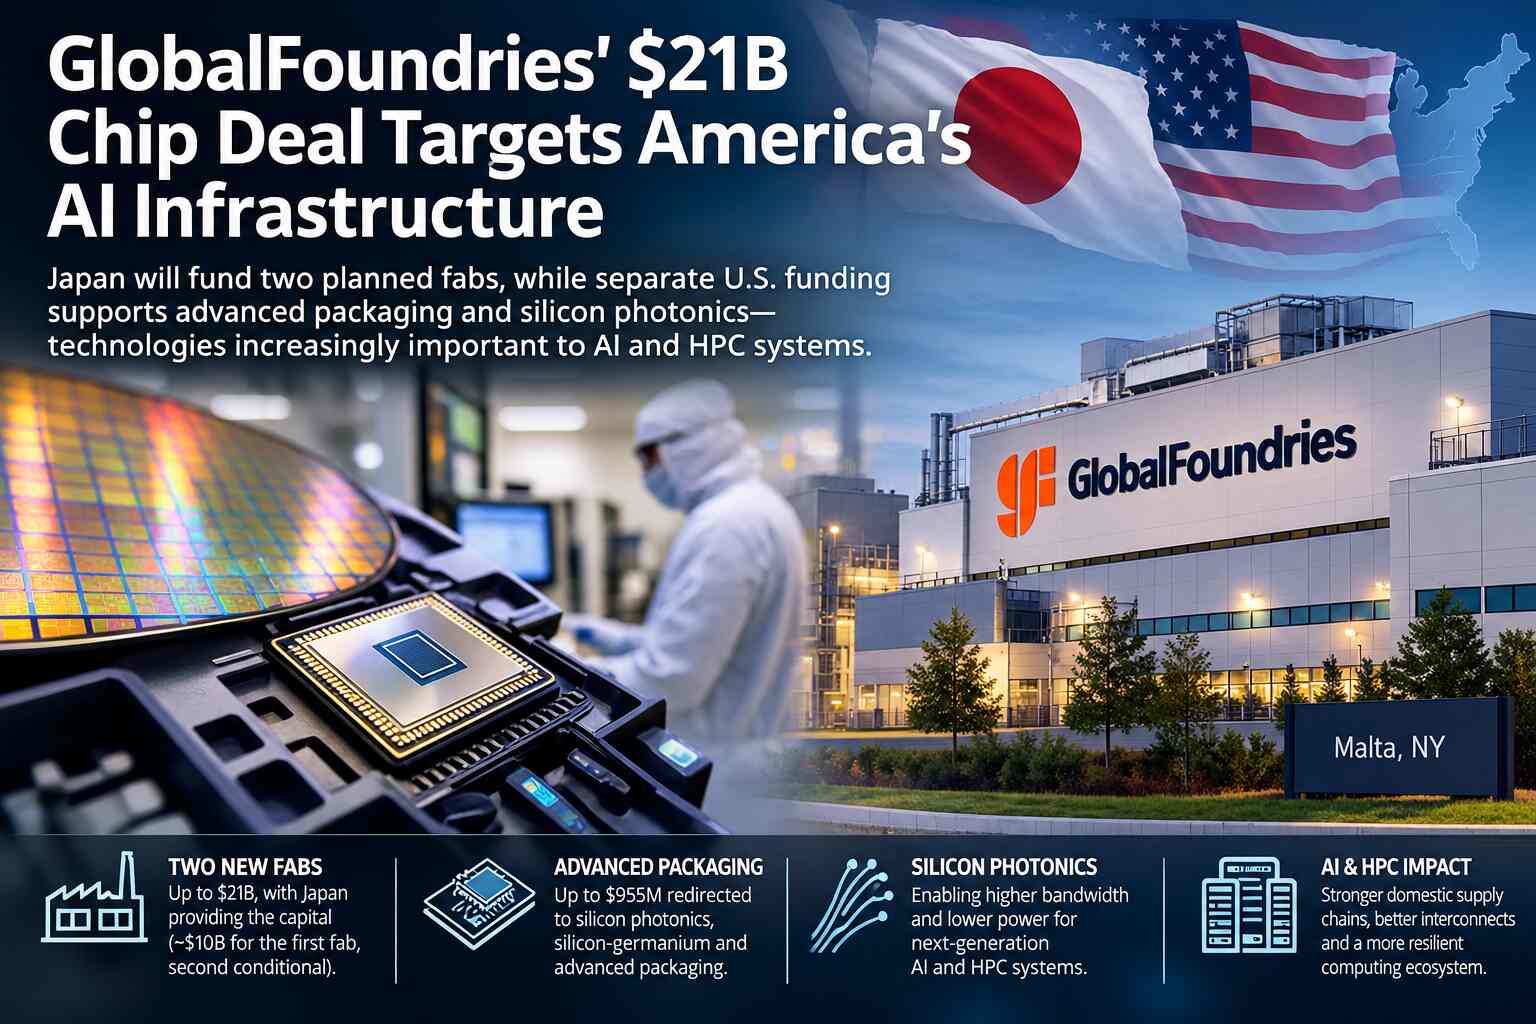
GlobalFoundries’ $21B chip deal targets America’s AI infrastructure
previous arrow
previous arrow
next arrow
next arrow
 
Shadow
NVIDIA wants AI factories online in 14 days, but the infrastructure bottlenecks haven’t disappeared
Featured

NVIDIA wants AI factories online in 14 days, but the infrastructure bottlenecks haven’t disappeared

Deckard, Staff Editor October 21, 2026, 10:00 am


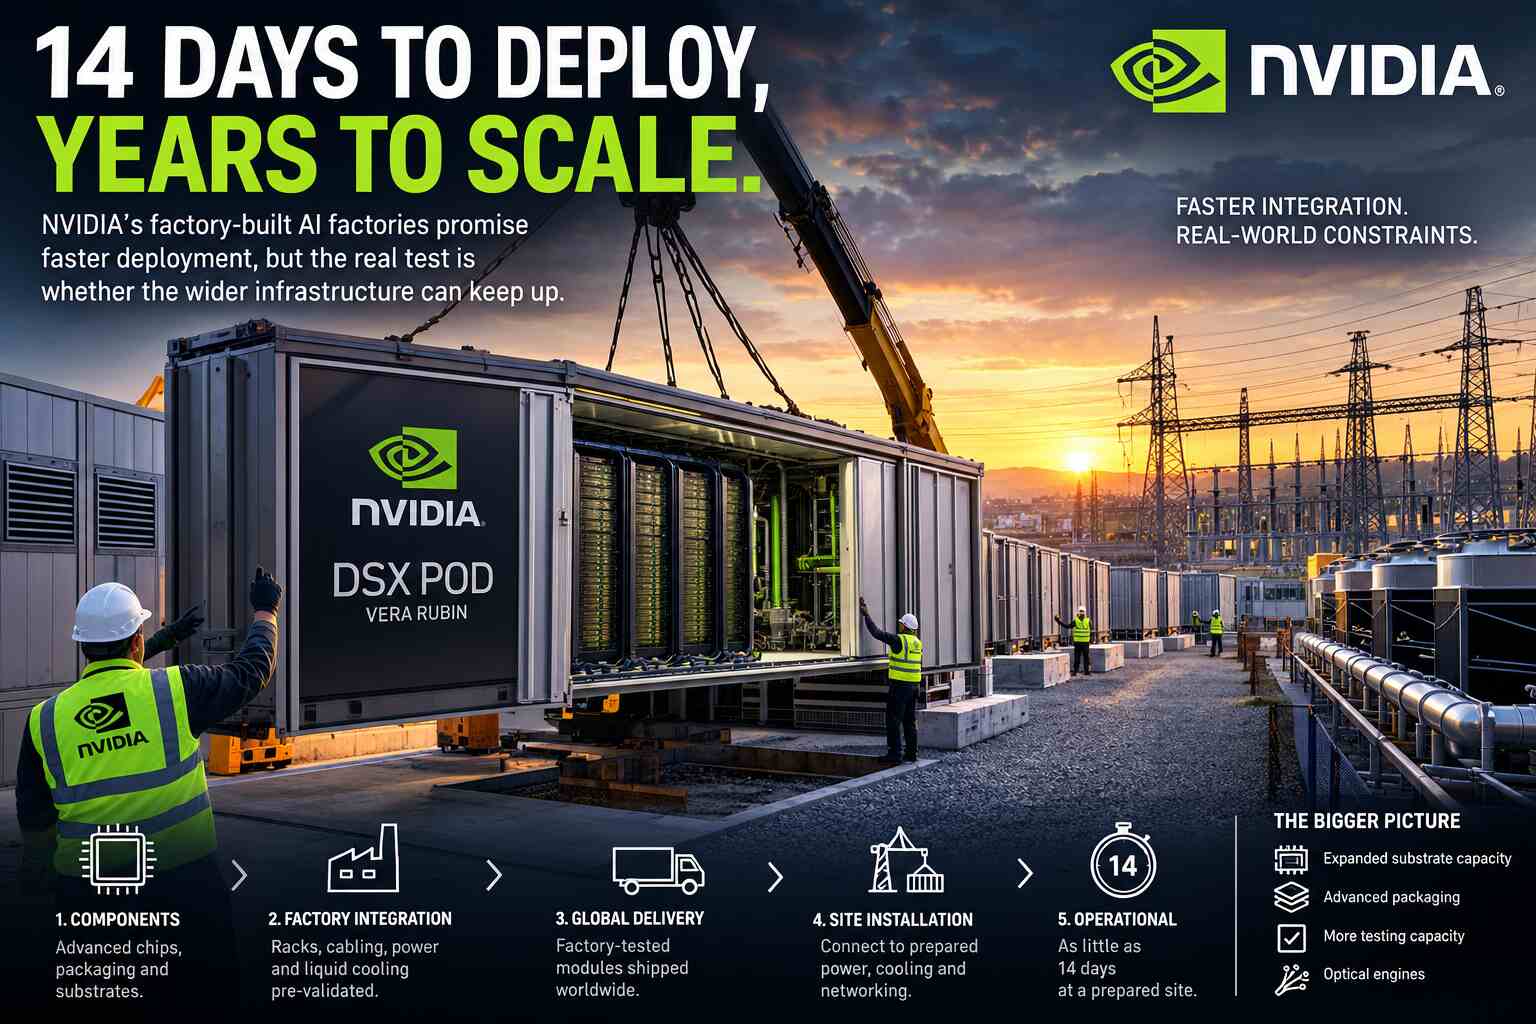
NVIDIA is taking on a broader role in the artificial intelligence infrastructure market, shifting from a primary supplier of processing units to an architect of standardized, factory-integrated computing solutions. Through the introduction of the DSX POD reference design at GTC Berlin, the company aims to streamline the deployment of AI supercomputers, potentially reducing installation timelines at prepared sites from six months to fourteen days. Furthermore, by concurrently announcing strategic supply-chain investments in semiconductor substrates, advanced packaging, testing, and optical engines, NVIDIA is working to accelerate the entire lifecycle from manufacturing to operational output. While these initiatives offer a repeatable framework for infrastructure development, the industry must still navigate the persistent tension between the rapid assembly of computing hardware and the external dependencies, such as grid capacity and site readiness, that remain critical to project success.

“We are in the midst of the largest infrastructure buildout in human history. Demand is extraordinary. Capacity is the constraint,” said Jensen Huang, founder and CEO of NVIDIA. “Our supply chain partners are the world’s best manufacturers. I’m grateful they are expanding capacity around the globe to scale production and help us deliver the AI supercomputing systems powering this new industrial revolution.”

From GPU systems to factory-built AI infrastructure

NVIDIA’s DSX POD concept shifts substantial integration work away from the customer’s data center and into a controlled manufacturing environment. Participating partners assemble the computing systems, complete rack-to-rack cabling, install wiring and piping, and conduct functional validation before the modules are shipped.

The delivered units are designed to connect to a prepared site’s power, cooling, networking, and supporting infrastructure. Instead of coordinating every stage of rack installation and system integration at the destination, operators can perform much of that work in parallel with site preparation.

NVIDIA is working with a broad ecosystem of manufacturers and infrastructure companies, including Dell Technologies, Hewlett Packard Enterprise, Lenovo, Foxconn’s Ingrasys operation, Bull, Quanta Cloud Technology, Schneider Electric, Vertiv, Eaton, and others. Worldwide deliveries are planned to begin in early 2027.

This is more than a packaging change. It represents an attempt to make large-scale AI computing deployments resemble a repeatable industrial production process rather than a series of bespoke data center projects.

For high-performance computing operators, standardization could reduce integration variability, simplify validation, and make it easier to plan capacity additions. Factory testing may also identify configuration problems before equipment reaches an operational facility, where troubleshooting can be more expensive and disruptive.

However, DSX POD is a reference design delivered through NVIDIA’s partners, not a turnkey data center that NVIDIA independently constructs from the ground up. The distinction matters: manufacturing, transportation, site readiness, commissioning, and operational support remain distributed across the supply chain.

The 14-day promise begins where the hardest infrastructure work may already be finished

NVIDIA’s headline deployment claim requires careful interpretation.

The company compares a conventional deployment period of approximately six months with a target of as little as 14 days at a prepared site. The shorter interval benefits from moving integration and validation into the factory and reducing the amount of work required after delivery.

But the clock does not encompass the entire process of establishing an AI data center.

Land acquisition, permitting, civil engineering, grid connections, electricity procurement, facility construction, and transportation are not eliminated by preassembling computing infrastructure. Nor does a standardized module guarantee that every destination has sufficient electrical capacity, cooling performance, network connectivity, or space for the intended deployment.

These constraints have become increasingly consequential as AI infrastructure grows from individual server installations into facilities demanding hundreds of megawatts or more.

A containerized system can arrive ready for connection, but it cannot manufacture a missing grid connection. Factory validation can reduce integration risk, but it cannot resolve a local permitting dispute or guarantee that the required power is available when the equipment arrives.

The distinction between installation time and total project delivery time should therefore remain central to evaluating NVIDIA’s claim.

For operators with prepared sites and established infrastructure, the approach could substantially shorten the path to productive compute. For projects still waiting on substations, transmission upgrades, or construction approvals, the benefits may be limited by the slowest unresolved dependency.

NVIDIA is also investing in the supply chain behind the factory

The DSX POD announcement is only one part of the strategy. NVIDIA’s accompanying supply-chain plans target manufacturing capabilities that help determine how quickly advanced computing systems can be produced in volume.

The company identified agreements and expansion plans involving six partners:

  • IBIDEN: An expansion of substrate capacity at its Ono Plant in Japan, with additional capacity expected to begin ramping in the first quarter of 2028.
  • Samsung Electro-Mechanics: Additional substrate supply from existing South Korean operations, alongside planned upgrades and new facilities.
  • Unimicron: Expanded substrate capacity, with additional capacity targeted for the second quarter of 2027 and full capacity expected around mid-2028.
  • Amkor Technology: Plans to increase advanced packaging capacity by more than 300% by the end of 2028.
  • King Yuan Electronics, or KYEC: New U.S. testing facilities supported by a $1.1 billion capacity-reservation advance from NVIDIA, with high-volume production targeted for April 2027.
  • Siliconware Precision Industries, or SPIL: A target to expand optical-engine capacity for co-packaged optics by 15 times by mid-2027, with a further doubling targeted by the end of 2028.

NVIDIA also outlined an aggregate target to increase substrate capacity 2.5-fold over three years through these and other initiatives.

The commitments address important stages of the manufacturing chain. Substrates provide the physical and electrical foundation for advanced semiconductor packages. Advanced packaging enables increasingly complex integration of computing components. Testing capacity is necessary to validate manufactured devices, while optical engines support high-bandwidth data movement within and between computing systems.

These capabilities are important because an AI supercomputer is not simply a collection of powerful processors. Its performance depends on the coordinated operation of compute, memory, interconnects, networking, storage, power delivery, cooling, and software.

A shortage in one critical component can delay the delivery of an otherwise complete system.

Yet the announcements should not be interpreted as proof that the semiconductor supply chain has been fully secured. Several targets extend through 2028, some financial commitments remain undisclosed, and the $1.1 billion KYEC advance is one specific arrangement rather than a disclosed total for NVIDIA’s supplier expansion.

Nor do the announced plans establish that every constraint involving wafer fabrication, high-bandwidth memory, or other advanced packaging capacity has been resolved.

The timelines reveal a gap between deployment ambitions and manufacturing capacity

The relationship between the two announcements is particularly revealing.

DSX POD deliveries are scheduled to begin in early 2027, while several major supply-chain expansions will take longer to mature. KYEC’s U.S. testing facilities target high-volume production in April 2027. Unimicron’s additional capacity is expected in the second quarter of 2027, while important substrate and advanced-packaging milestones extend into 2028.

That sequencing means the initial DSX POD deployments must rely on existing capacity and the supply available as systems are manufactured. The newly announced expansions may support subsequent growth, but they cannot automatically be credited with enabling the first shipments.

This is an important distinction when evaluating the broader strategy. NVIDIA is pursuing two complementary objectives: reducing the time required to assemble and deploy computing infrastructure, and increasing the manufacturing capacity required to supply that infrastructure over time.

The two efforts reinforce each other, but they operate on different schedules.

The practical test will be whether supplier expansions arrive on time, component yields and qualification meet requirements, and manufacturing output translates into completed systems that customers can actually deploy.

Power and cooling remain fundamental design constraints

The broader NVIDIA DSX platform also addresses how AI factories use electricity and manage heat.

Modern accelerated-computing systems concentrate substantial power consumption into dense racks. Liquid cooling transfers heat away from processors and other components, while facility-level systems must ultimately reject that heat into the surrounding environment.

NVIDIA says its DSX reference designs can use closed-loop liquid cooling and dry coolers to reduce facility cooling-water consumption by up to 100% under suitable conditions. At a hypothetical two-gigawatt deployment, the company estimates potential savings of 54 million liters of water per day compared with conventional cooling towers.

That figure concerns cooling water, not the facility’s total water footprint. Local climate also matters: extreme heat can require supplemental mechanical cooling, changing the system’s energy consumption and operating economics.

NVIDIA separately says its DSX MaxLPS software can reduce the power required to generate the same number of AI tokens by up to 30% through dynamic allocation of power within a provisioned budget.

These are potentially meaningful improvements, particularly for operators trying to maximize useful computation within fixed electrical limits. But the figures describe different outcomes and should not be combined into a single efficiency claim. Actual results will depend on workloads, system configuration, environmental conditions, and the assumptions underlying each comparison.

Reducing cooling-water demand or improving power utilization also does not create new grid capacity. Those improvements can help a facility operate more efficiently within its available resources, but they do not replace the infrastructure required to deliver electricity reliably.

Faster installation does not necessarily mean faster grid access

For the AI infrastructure industry, the distinction between equipment readiness and site readiness is becoming increasingly important.

A factory-integrated system may simplify construction and commissioning, but the facility still requires adequate electrical supply, cooling infrastructure, networking, and operational support. In markets where grid connections and permitting are already delaying projects, the limiting factor may sit outside the computing architecture altogether.

NVIDIA’s DSX Flex approach, which is intended to help AI factories adjust their power consumption to support grid operations, addresses part of that relationship between computing workloads and electricity supply. Flexible power demand can potentially help operators coordinate workloads with grid conditions.

It should not, however, be confused with a guaranteed grid connection or a substitute for transmission and generation investment.

The same distinction applies to semiconductor manufacturing. Expanding substrates, packaging, testing, and optical-engine production is strategically useful, but individual component expansions do not guarantee that every other part of the manufacturing chain will scale at the same rate.

The infrastructure challenge is systemic. Faster modules, more efficient cooling, improved power management, and greater component capacity each address part of the problem. None independently removes all the dependencies that determine how quickly a large AI computing facility can become operational.

The commercial question remains unanswered

NVIDIA’s announcements establish a direction for infrastructure development, but important commercial details remain undisclosed.

The company has not announced DSX POD pricing, a complete order book, or enough customer commitments to establish how quickly the containerized format will be adopted. Its partner ecosystem provides a potential manufacturing and delivery network, but participation in a reference design is not equivalent to a confirmed customer purchase.

The economics will depend on more than the speed of installation. Buyers will need to evaluate capital costs, transport requirements, facility integration, maintenance, hardware utilization, energy expenses, cooling performance, and the ability to expand capacity without introducing new operational constraints.

Standardization could reduce deployment variability and shorten the time before infrastructure begins generating revenue. However, those benefits must be measured against actual deployment results rather than inferred from vendor targets alone.

The first production deployments will provide important evidence about the approach’s practical limits. Useful measurements will include delivery schedules, commissioning duration, system availability, power utilization, cooling performance, and the time between equipment arrival and sustained production workloads.

Those results will help determine whether factory-built AI infrastructure becomes a widely adopted deployment model or remains best suited to a narrower set of large, well-prepared projects.

An industrial strategy, not a shortcut around physics

NVIDIA’s recent announcements signal a strategic shift toward a more integrated model for AI infrastructure. By standardizing deployable systems and incentivizing the expansion of critical manufacturing capabilities, the company aims to streamline the development lifecycle.

For operators, the potential advantages, including reduced on-site integration, greater configuration consistency, and a more predictable transition to production, are significant. However, the projected 14-day deployment timeline must be viewed as an optimization of the assembly phase, contingent upon pre-existing site readiness rather than a comprehensive timeline from project inception. Similarly, the announced supply-chain expansions represent a series of long-term milestones that, while promising, do not immediately resolve existing industry shortages.

Ultimately, the success of this initiative will depend on NVIDIA’s ability to foster a repeatable, industrialized approach to large-scale computing deployment. If executed effectively, these measures could significantly compress the infrastructure development cycle; however, the persistent bottlenecks in grid capacity, permitting, and construction remain external variables that will ultimately dictate the pace of industry expansion.
Amazon’s €16 billion Germany pledge has a €4.8 billion AI question: Where is the new compute?
Featured

Amazon’s €16 billion Germany pledge has a €4.8 billion AI question: Where is the new compute?

Tyler O'Neal, Staff Editor October 20, 2026, 4:00 pm

Amazon’s 2027 investment announcement aggregates diverse initiatives across cloud infrastructure, satellite development, logistics, and media production. For the supercomputing trade, the primary concern lies in determining the actual computational capacity, power requirements, and incremental AI infrastructure underlying these headline figures.

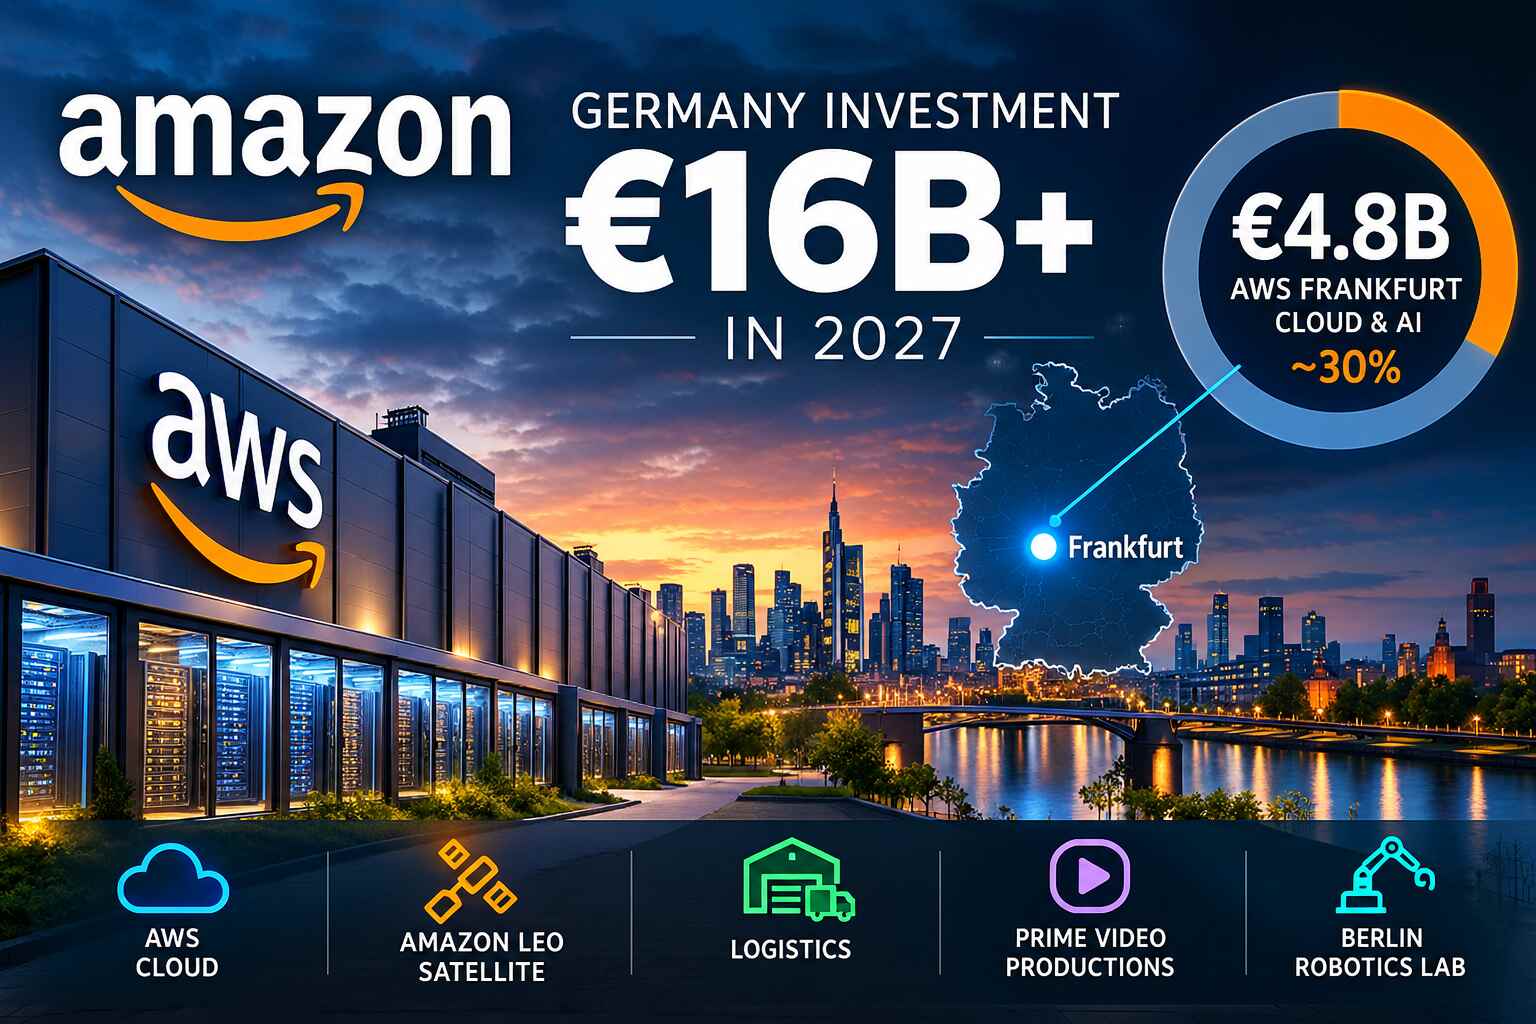
While Amazon has announced a €16 billion ($17.9 billion) investment in Germany for 2027, marking one of its most significant annual commitments, the figure requires critical scrutiny regarding its implications for high-performance computing and artificial intelligence. Only €4.8 billion is specifically allocated to the expansion of Amazon Web Services’ (AWS) Frankfurt cloud region and AI infrastructure.

This distinction is vital, as the broader investment encompasses diverse sectors including satellite broadband, logistics, media production, and robotics research. Consequently, the announcement should not be interpreted as a €16 billion AI infrastructure program. 

Although this investment occurs as demand for AI computing fundamentally reshapes data-center construction and power procurement, the proposal leaves several technical questions unresolved. Specifically, it remains unclear how much additional computing capacity the expansion will provide and to what extent this spending represents genuinely incremental investment. For an industry currently constrained by power availability and the economics of deploying advanced accelerators, these technical details are far more significant than the headline investment figure.

The €4.8 billion question

Amazon says €4.8 billion will go toward expanding AWS’s Frankfurt region and AI infrastructure. That represents approximately 30% of the announced German investment package.

However, the company has not disclosed the division between AI-specific infrastructure and general-purpose cloud capacity. Nor does the announcement provide a detailed breakdown of additional electrical capacity, accelerator deployments, server installations, or expected compute throughput.

Without those figures, it is difficult to assess what the investment will mean for the practical availability of AI computing resources in Germany.

A capital expenditure figure alone cannot establish how much useful computation will become available. The result depends on the infrastructure purchased, the cost of power and cooling, the architecture of the deployed systems, network and storage performance, and how efficiently workloads use the resulting capacity.

For HPC users, the relevant questions extend beyond the number of GPUs installed. Large-scale AI training and scientific simulation depend on the interaction of compute, memory bandwidth, high-speed interconnects, storage throughput, and software efficiency. Additional data-center investment does not automatically translate into a proportional increase in usable computational performance.

Amazon has not provided sufficient technical detail to quantify that relationship for the Frankfurt expansion.

A familiar pledge, with an unresolved baseline

The latest announcement also raises a financial question: how much of the €16 billion represents new investment beyond Amazon’s existing commitments?

In June 2024, Amazon announced a €10 billion investment commitment for Germany covering cloud infrastructure and logistics, including €8.8 billion for AWS data centers. Separately, AWS committed €7.8 billion through 2040 to establish its European Sovereign Cloud in Germany.

The new announcement identifies €4.8 billion for AWS Frankfurt expansion in 2027. However, the available announcement and reporting do not establish whether this amount is entirely additional to earlier commitments or whether some spending falls within previously announced programs.

That uncertainty should not be mistaken for evidence of double counting. Large infrastructure programs often span multiple years, and companies can announce annual spending plans that sit within longer-term investment commitments. The issue is that the relationship between these figures has not been sufficiently clarified.

The €16 billion headline also covers an entire year rather than a multi-year program. It therefore cannot be compared directly with investment commitments extending over a decade or more without accounting for differences in scope and timing.

Amazon has said it has invested more than €100 billion in Germany since 2010. That cumulative figure includes its wider operations, rather than representing cloud infrastructure spending alone.

For policymakers and investors evaluating Europe’s AI infrastructure buildout, the useful comparison is not simply one national pledge against another. It is the amount of new capacity and productive infrastructure being delivered relative to the money committed.

Frankfurt’s power problem

The absence of detailed power information is one of the most significant gaps in the announcement.

Frankfurt is a major European data-center hub, and additional AI infrastructure must contend with the practical requirements of electricity supply, grid connections, cooling systems and facility construction. High-density AI deployments place particularly demanding requirements on electrical distribution and thermal management.

The announcement does not specify how much additional power the €4.8 billion expansion will require, where that power will come from, or whether the necessary grid capacity and connections are secured.

These are not peripheral engineering details. They determine whether planned compute capacity can be delivered on schedule.

AI infrastructure operators must coordinate power availability with the installation of servers, accelerators, networking equipment, and cooling systems. A facility can be physically constructed while remaining unable to operate its full planned computing load if electrical connections or other critical infrastructure are delayed.

The same constraints influence the economics of HPC facilities. Electricity costs, cooling efficiency and the ability to operate equipment at its intended utilization rate affect the cost of delivering computation. The headline capital expenditure figure reveals little about those operating realities.

AWS has not provided enough information to determine how these considerations will shape the Frankfurt expansion.

A broader industrial package

The German commitment extends well beyond cloud computing.

Amazon plans to continue satellite broadband development through its Amazon Leo program, including a partnership with Arianespace for 24 launches. The investment package also includes logistics projects expected to create more than 3,000 jobs, new Prime Video productions and a second robotics and AI research laboratory in Berlin.

Fulfillment-center modernization is also part of the broader program. Work at facilities in Bad Hersfeld, Dortmund and Werne is scheduled for completion in 2027, while projects in Koblenz, Pforzheim and Rheinberg continue through 2028.

These investments may have economic and technological value, but they are not interchangeable with spending on large-scale AI compute infrastructure. Satellite development, warehouse automation, media production and cloud data centers have different capital requirements, operating models and performance measures.

That distinction is important when assessing national investment announcements. A broad package can demonstrate a company's commitment to a market without establishing how much additional AI capacity will be available to researchers, businesses or public-sector customers.

The announcement also identifies more than 3,000 expected jobs associated with logistics projects. Those positions should not be characterized as new AI engineering or data-center jobs.

Europe’s cloud and AI capacity race

The AWS expansion arrives as European governments and companies seek stronger digital infrastructure and greater control over the computing resources used for sensitive workloads.

Cloud capacity has become an increasingly important component of scientific research, industrial simulation, generative AI and enterprise computing. Sovereign-cloud initiatives add requirements concerning data handling, operational control and regulatory compliance, potentially influencing where infrastructure is deployed and how services are delivered.

For Germany, expanding AWS capacity could strengthen the local availability of cloud services and AI resources. But the extent of that benefit will depend on what Amazon actually deploys, how quickly the capacity becomes operational, and which services receive the additional resources.

The European Sovereign Cloud commitment adds another dimension. Its relationship to the new Frankfurt spending has not been disclosed in sufficient detail to establish how much of the 2027 investment supports sovereign-cloud capabilities.

That question matters because infrastructure spending can serve multiple objectives simultaneously. General cloud expansion, AI accelerator deployment, and sovereign-cloud requirements may overlap operationally, but their respective costs and benefits should not be assumed to be identical.

The questions Amazon still needs to answer

For the HPC and AI infrastructure community, several disclosures would make the announcement considerably more useful.

First, how many additional megawatts of IT load will the Frankfurt expansion support, and what is the expected schedule for bringing that capacity online?

Second, how much of the €4.8 billion is allocated specifically to AI infrastructure, including accelerators, high-speed networking, storage and supporting systems, rather than general-purpose cloud expansion?

Third, how much additional compute capacity will the investment deliver, and what performance or utilization measures will AWS use to demonstrate the result?

Fourth, what power procurement and grid-connection arrangements will support the expansion, and how will cooling and energy efficiency affect the deployment?

Finally, is the €4.8 billion commitment entirely incremental to Amazon’s previous German investment pledges, and what portion of the €16 billion package represents spending that would otherwise have occurred in the ordinary course of business?

Clear answers would allow analysts to evaluate the announcement as an infrastructure program rather than relying on a headline financial figure.

The verdict: Measure the compute, not the pledge

While Amazon’s announcement is a significant development for the German cloud market and the broader expansion of European AI infrastructure, the €4.8 billion allocation for Frankfurt serves primarily as a general investment signal, particularly given that the overarching €16 billion commitment encompasses a wide array of unrelated business activities.

Consequently, this announcement does not yet function as a definitive technical blueprint for the next generation of European AI computing capacity. Until Amazon discloses granular details regarding incremental investment, specific power requirements, hardware specifications, and projected capacity, it remains difficult to quantify the actual computational output or the deployment timeline. For supercomputing professionals, the true measure of such an infrastructure commitment lies not in the headline figures of a press release, but in the operational capacity delivered, the sustainability of the required power, and the tangible performance gains realized. Currently, Amazon has provided the financial narrative, but the essential technical substantiation remains absent.

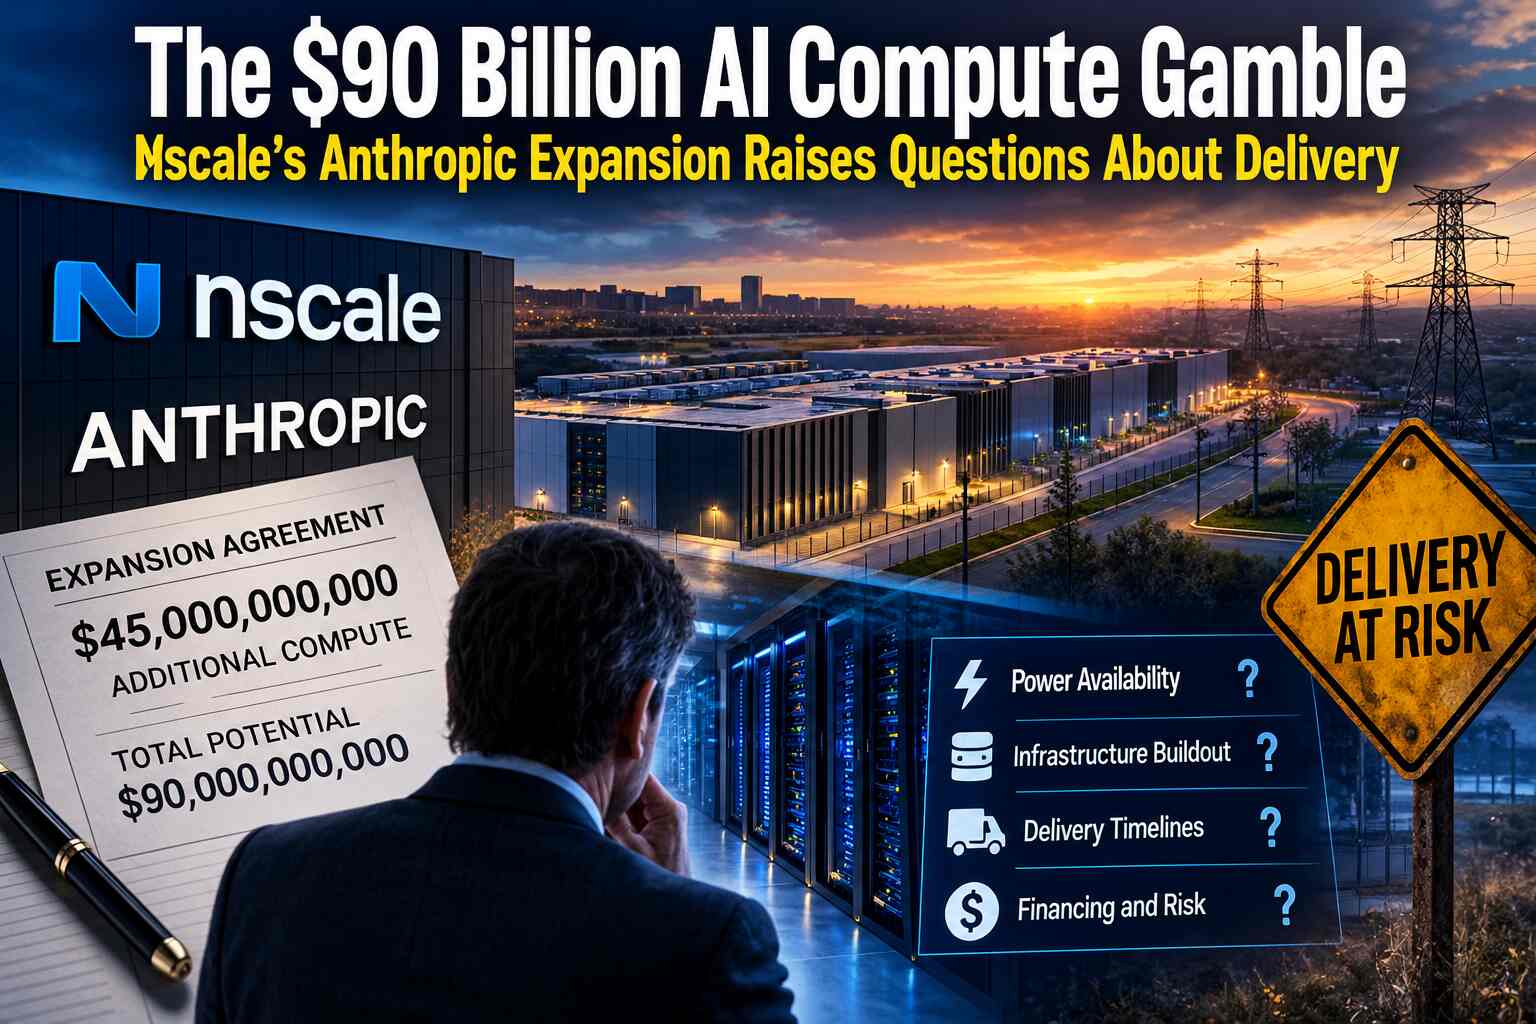
The $90 billion AI compute gamble: Nscale’s Anthropic expansion raises questions about delivery
Featured

The $90 billion AI compute gamble: Nscale’s Anthropic expansion raises questions about delivery

CHRIS O'NEAL, PUBLISHER October 19, 2026, 4:00 pm

A second reported $45 billion agreement would deepen Nscale’s dependence on Anthropic, while financing, power availability, and construction remain critical tests of the AI infrastructure boom.

The AI infrastructure industry has demonstrated a remarkable aptitude for announcing massive financial commitments; however, the more significant challenge lies in translating these figures into operational computing systems.

This dichotomy defines the potentially vast expansion involving Nscale, an AI infrastructure provider backed by Nvidia, and Anthropic, the developer of Claude. On October 19, Bloomberg reported that the two companies are negotiating a second cloud computing agreement worth about $45 billion. This proposed deal would support a new 460-megawatt facility at Nscale’s Monarch Compute Campus in West Virginia and may grant Anthropic a right of first refusal on a third facility.

While Reuters covered the report, the outlet could not independently verify the negotiations, and neither company has confirmed the agreement. As a result, this remains an ongoing negotiation rather than a finalized contract.

Ultimately, the broader narrative transcends the timeline of this agreement. Nscale’s own public offering disclosures illuminate the primary challenge facing the AI infrastructure sector: contracted demand often outpaces the physical infrastructure, financing, and operational capabilities necessary to fulfill such commitments.

A $103.4 billion backlog with a delivery problem

Nscale’s September IPO filing reported approximately $103.4 billion in total contracted value as of August 2026, up from roughly $38 billion at the end of 2025. The company’s disclosed agreements include up to approximately $43.8 billion associated with Microsoft and $44.6 billion associated with Anthropic.

Together, those two customers represent roughly 85% of the reported contracted value.

The operational figures tell a very different story. According to the filing figures summarized in reporting on the prospectus, approximately $2.6 billion of the $103.4 billion total was active as of late August. That is about 2.5% of the reported contract value.

The distinction requires care: contracted value is not the same as recognized revenue, cash in the bank, or a measure of computing capacity alone. The agreements span multiple years, and their value depends on services being delivered over time. A low proportion of active contract value does not, by itself, establish that the remaining commitments will fail.

It does, however, expose the scale of the execution challenge.

Nscale must secure financing, obtain hardware, construct facilities, arrange dependable power and cooling, commission systems, and deliver capacity according to contractual milestones. Until those steps occur, much of the reported backlog remains a future obligation rather than an operating AI cloud business.

For HPC customers, the difference is fundamental. A projected GPU deployment is not a production cluster. A building announcement is not a commissioned supercomputer. And a contract for computing capacity is not proof that the capacity will be available when a customer needs it.

The first Anthropic agreement carries conditions

The proposed second agreement would build on an existing Anthropic commitment valued at approximately $44.6 billion, covering 460 MW of computing capacity over six years at the Monarch campus.

Nscale’s IPO disclosures describe important conditions surrounding that first agreement. The company had not secured binding financing commitments sufficient to fund the required buildout, and it had not secured all the long-term chip supply needed to perform its obligations. The filing also describes stringent delivery milestones and provisions allowing Anthropic to cancel affected later tranches without penalty under specified circumstances.

These are not minor details buried beneath an otherwise impressive contract value. They help determine who bears the risk if financing slips, hardware arrives late, construction falls behind schedule, or a facility cannot provide the promised service.

A second agreement could create an even larger opportunity for Nscale. But if the reported terms resemble the first arrangement, it could also increase the amount of future infrastructure the company must finance and deliver for the same customer.

That is the difference between growing a backlog and diversifying a business.

If the second agreement closes at approximately $45 billion, Anthropic’s potential contracted value with Nscale could approach $90 billion. Against a reported total backlog of $103.4 billion, that would represent an extraordinary concentration in one customer, assuming the amounts are additive and the other commitments remain unchanged.

The figure should not be mistaken for guaranteed revenue. It represents the potential scale of the contractual relationship, not cash already earned or infrastructure already operating.

A 460-megawatt facility is an engineering undertaking

The Monarch project illustrates why AI infrastructure cannot be evaluated solely by counting accelerators or comparing announced capital commitments.

A 460 MW data-center deployment requires much more than racks of Nvidia Vera Rubin systems. It needs electrical infrastructure capable of delivering power reliably, cooling systems designed for sustained high-density computing, network fabrics that connect accelerators at scale, storage infrastructure able to feed workloads, and operational systems to monitor and maintain the entire environment.

Those subsystems must work together.

In large distributed AI training jobs, a shortage of power or a cooling limitation can prevent an otherwise expensive cluster from reaching its intended operating capacity. Network congestion, insufficient storage throughput, failed components, or poorly coordinated system software can further reduce the useful work delivered by the installed hardware.

The facility must also be commissioned in stages. Equipment deliveries, electrical acceptance testing, cooling validation, networking integration, and workload qualification all have to align with the promised service schedule.

That makes the reported second 460 MW facility a substantial construction and systems-integration challenge, not merely another order for GPUs.

The schedule matters, too. The existing Monarch deployment has been associated with a planned rollout of next-generation Vera Rubin systems beginning in late 2027. A second facility would introduce additional dependencies involving hardware availability, construction progress, and power delivery. Neither the proposed deal nor its final implementation schedule has been confirmed.

For the HPC community, the relevant question is not simply how many accelerators Anthropic may eventually rent. It is how much usable compute Nscale can bring online, when it can deliver it, and at what level of reliability.

Microsoft’s withdrawal underscores the power constraint

The concerns are not hypothetical.

On October 19, Reuters reported that Microsoft had withdrawn from a planned Nscale data-center project in Loughton, England, after delays involving access to the electricity grid. Reuters’ Breakingviews analysis highlighted the wider risk for infrastructure providers that have signed large commitments before all the necessary capacity is ready.

The withdrawal concerns a particular project; it does not establish that Microsoft has abandoned its broader relationship with Nscale or that the Monarch campus will suffer the same outcome. Nevertheless, it demonstrates that access to electricity can become a decisive constraint even when a major customer and a technology supplier are already lined up.

Monarch also has an energy dimension of its own. The vetting material identifies Caterpillar natural-gas generator sets as part of the campus’s planned behind-the-meter power strategy. On-site generation may provide an alternative or supplement to grid supply, but it introduces its own engineering, fuel-supply, permitting, emissions, and operating considerations.

A generator installation is not automatically equivalent to a fully engineered, permitted, and dependable power system for a campus operating at hundreds of megawatts.

The question is whether the entire energy plan can support the facility’s commissioning schedule and sustained computing demand. That requires more than a projected capacity figure.

For an industry increasingly constrained by electricity availability, the power system is part of the supercomputer.

The financial structure deserves the same scrutiny as the hardware

Nscale’s proposed public offering adds another layer to the story.

The company’s filing outlined a planned listing and a potential fundraising target of up to $3 billion, with reporting placing its valuation ambitions as high as $35 billion. Its first-half 2026 financial results showed revenue of approximately $140.6 million and a net loss of approximately $1.02 billion, compared with revenue of $10.4 million and a loss of approximately $369 million in the same period a year earlier.

Those figures reflect a company investing heavily in growth, but they also demonstrate the distance between its current financial performance and the scale implied by its contracted commitments.

The proposed second Anthropic deal arrives at a time when Nscale needs to convince investors that its future obligations can become a functioning, revenue-generating infrastructure business.

That timing warrants scrutiny, not an assumption of misconduct. The reported negotiations may represent genuine customer demand and a commercially valuable expansion. But an unconfirmed agreement should not be treated as though it has already improved the company’s cash flow, funded its construction programme or reduced its execution risks.

Investors need to distinguish signed agreements from negotiations, conditional commitments from unconditional ones, and announced financing from binding funding available when construction bills come due.

Nvidia’s position is also relevant. The company is both a major participant in the AI hardware ecosystem and a reported $1 billion investor in Nscale’s pre-IPO convertible financing. That relationship does not invalidate Nscale’s business, but it illustrates how closely capital providers, accelerator suppliers, and AI infrastructure operators can be connected.

The industry’s expansion increasingly relies on an interconnected group of companies funding, supplying and purchasing capacity from one another. Such relationships can accelerate deployment, but they also make it essential to understand who ultimately bears the financial risk if expected demand, construction schedules or equipment deliveries change.

Anthropic has options. Nscale must deliver.

Anthropic’s broader computing strategy makes the proposed expansion particularly interesting.

The AI developer has pursued capacity through multiple cloud and infrastructure relationships, including major arrangements involving Google, Amazon Web Services and other providers. Its reported negotiations with Nscale therefore sit within a wider effort to secure enough computing capacity for future model development and deployment.

For Anthropic, securing future capacity across several providers can reduce dependence on any single infrastructure project, although individual agreements may still impose substantial commitments.

For Nscale, the calculus is different. The company must build the facilities and procure the systems that turn those commitments into services. If the customer has contractual rights to cancel affected tranches when specified milestones are missed, Nscale faces a potential mismatch between infrastructure costs and the revenue it expects to earn.

That asymmetry is central to the story. Anthropic is competing to secure future compute. Nscale is competing to demonstrate that it can supply it.

A second contract could strengthen the commercial relationship, but it would not automatically resolve the financing, power, construction and delivery questions surrounding the first.

What HPC operators should watch next

Several milestones will reveal more than another headline about contract value.

First, watch for confirmation of the proposed second agreement and its actual terms. The critical details include delivery dates, cancellation provisions, capacity milestones, and whether the arrangement depends on financing or other conditions.

Second, look for evidence of binding project financing and secured hardware supply. A credible delivery plan must connect the funding timetable with equipment procurement and construction milestones.

Third, track physical progress at Monarch: permits, power availability, facility commissioning, cooling validation, networking readiness, and the number of megawatts that are actually serving workloads.

Fourth, examine the distinction between installed hardware and usable compute. Accelerator counts alone do not establish delivered performance. HPC customers ultimately need reliable service, predictable availability, and systems capable of sustaining demanding workloads.

Finally, watch customer concentration. If Microsoft and Anthropic continue to account for most of Nscale’s contracted value, the company’s outlook will remain heavily influenced by the investment decisions and contractual rights of those two customers.

These are measurable questions. They offer a firmer basis for assessing the project than treating a potential $45 billion agreement as proof of future success.

The bottom line: Backlog is not compute

The AI industry necessitates substantial infrastructure investment, and Nscale’s reported negotiations with Anthropic underscore the magnitude of this demand. A second 460 MW facility at the Monarch campus could serve as a significant source of future computing capacity, contingent upon the finalization of the agreement and the successful financing, construction, and commissioning of the project.

However, as the second agreement remains unconfirmed, the conditional nature of the initial contract highlights that project execution is a critical challenge rather than a peripheral detail.

Nscale’s reported $103.4 billion backlog reflects the scale of the opportunity it is pursuing. Nonetheless, the modest percentage of active contract value, the reliance on a limited number of major customers, and the inherent complexities regarding financing and power procurement demonstrate why this opportunity cannot be assessed solely by its headline figure.

For the supercomputing industry, the definitive metric is not the valuation of a contract or the number of GPUs allocated for a future site. Rather, it is the computing capacity that can be reliably delivered, sustainably powered, and scaled effectively. In the realm of AI infrastructure, a multi-billion-dollar contract represents a promise; a fully operational supercomputer constitutes proof.

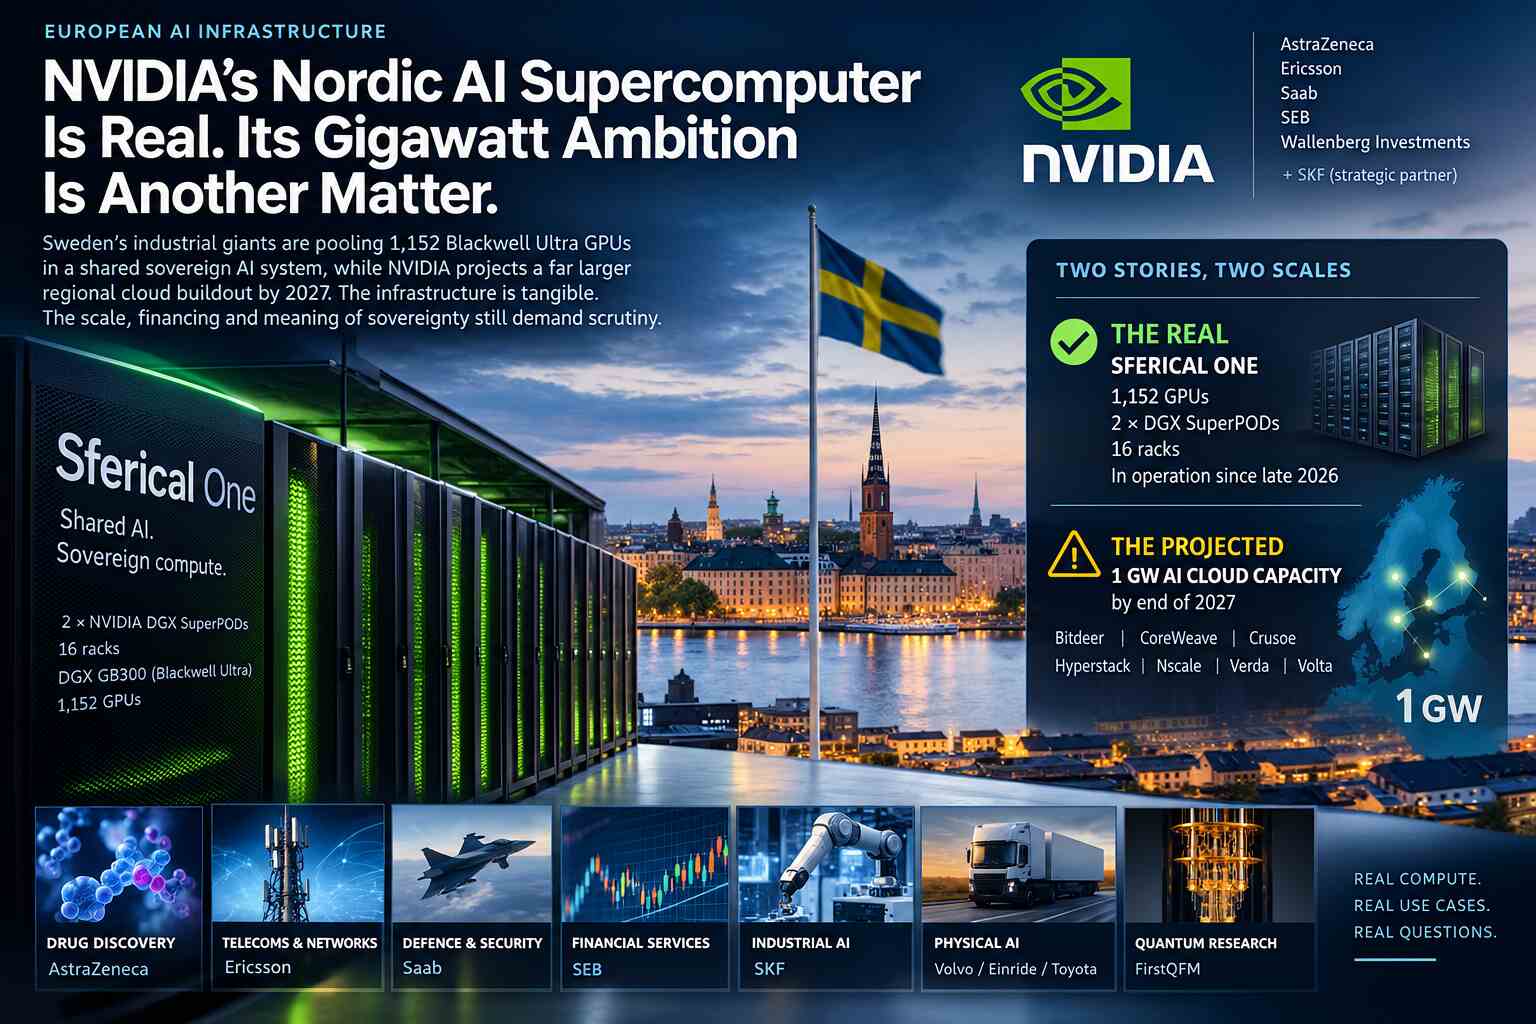
  • NVIDIA’s Nordic AI supercomputer is real. Its gigawatt ambition is another matter.
  • The AI supercomputer’s power problem is moving inside the rack: Delta pushes 800 VDC toward NVIDIA’s next generation
  • 1
  • 2
Page 1 of 2
POPULAR RIGHT NOW
  • 10,000 AI agents, 130 billion tokens and 88 hours: How OpenAI turned Navier–Stokes into a supercomputing workload
    10,000 AI agents, 130 billion tokens and 88 hours: How OpenAI turned Navier–Stokes into a supercomputing workload
  • Qualcomm enters the supercomputing arena as AWS partnership challenges Nvidia’s AI infrastructure dominance
    Qualcomm enters the supercomputing arena as AWS partnership challenges Nvidia’s AI infrastructure dominance
  • Fugaku goes inside the molecular machine: Supercomputer simulations reveal how kinesin knows which way to step
    Fugaku goes inside the molecular machine: Supercomputer simulations reveal how kinesin knows which way to step
  • From the Tibetan Plateau to California: Supercomputing reveals a hidden source of flood predictability
    From the Tibetan Plateau to California: Supercomputing reveals a hidden source of flood predictability
  • Supercomputing reconstructs the moon Venus may have lost
    Supercomputing reconstructs the moon Venus may have lost
  • Japanese supercomputer recreates the birth of the Universe’s monster black holes
    Visualization of the simulation by ATERUI III showing a rapidly growing black hole surrounded by gas. Red indicates areas of higher temperature. (Credit: Sunmyon Chon, Takaaki Takeda, 4D2U Project, NAOJ)
    Visualization of the simulation by ATERUI III showing a rapidly growing black hole surrounded by gas. Red indicates areas of higher temperature. (Credit: Sunmyon Chon, Takaaki Takeda, 4D2U Project, NAOJ)
  • China’s supercomputing push meets a harder problem: Teaching computers to keep asteroids honest
    China’s supercomputing push meets a harder problem: Teaching computers to keep asteroids honest
  • Alibaba’s superintelligence ambition puts supercomputing at the center of the AI race
    Alibaba’s superintelligence ambition puts supercomputing at the center of the AI race
  • AI’s trillion dollar compute race hits a hard limit: There isn’t enough power
    AI’s trillion dollar compute race hits a hard limit: There isn’t enough power
  • AI agents search 1.9 billion protein clusters, discover a new biological system
    AI agents search 1.9 billion protein clusters, discover a new biological system
THIS YEAR'S MOST READ
  • Wall Street wants to trade supercomputing power like oil
    Wall Street wants to trade supercomputing power like oil
  • Beamforming the future: BeammWave's 6G push signals the rise of orbital-terrestrial wireless networks
    Joakim Axmon
    Joakim Axmon
  • AI breaks conservation barriers: Australia’s Wildlife Observatory leverages supercomputing to protect biodiversity
    AI breaks conservation barriers: Australia’s Wildlife Observatory leverages supercomputing to protect biodiversity
  • Silicon spintronics brings the P-computer closer to reality
    Microscope image of a semiconductor-integrated spintronic test chip developed by researchers at Tohoku University and NIST. The device demonstrates the first silicon-integrated probabilistic bit (p-bit), a key building block for future large-scale probabilistic computers designed for AI and optimization workloads.
    Microscope image of a semiconductor-integrated spintronic test chip developed by researchers at Tohoku University and NIST. The device demonstrates the first silicon-integrated probabilistic bit (p-bit), a key building block for future large-scale probabilistic computers designed for AI and optimization workloads.
  • Hidden order, revealed at scale: Supercomputing, electron ptychography uncover the inner workings of relaxor ferroelectrics
    Hidden order, revealed at scale: Supercomputing, electron ptychography uncover the inner workings of relaxor ferroelectrics
  • Physics-trained ‘Digital Super Brain’ learns from supercomputers to accelerate discovery
    Physics-trained ‘Digital Super Brain’ learns from supercomputers to accelerate discovery
  • Memory has become the new compute: Why Micron, SK Hynix crossing $1 trillion matters to supercomputing
    Memory has become the new compute: Why Micron, SK Hynix crossing $1 trillion matters to supercomputing
  • Cosmic ambition at scale: UK’s supercomputer unlocks a 2.5 petabytes universe
    Cosmic ambition at scale: UK’s supercomputer unlocks a 2.5 petabytes universe
  • Huawei’s Tau Scaling ambition tests the limits of post-Moore semiconductor reality
    He Tingbo from HUAWEI delivered a keynote speech titled "New Semiconductor Path in Practice"
    He Tingbo from HUAWEI delivered a keynote speech titled "New Semiconductor Path in Practice"
  • Intel's Q1 results signal supercomputing surge driving Xeon momentum
    Intel's Q1 results signal supercomputing surge driving Xeon momentum
MOST READ OF ALL-TIME
  • Largest Computational Biology Simulation Mimics The Ribosome
    Details
    112843
    The amino acid (green) slithers into the chemical reaction center, moving through an evolutionarily ancient corridor of the ribosome (purple). The amino acid is delivered to the reaction core by the transfer RNA molecule (yellow).
    The amino acid (green) slithers into the chemical reaction center, moving through an evolutionarily ancient corridor of the ribosome (purple). The amino acid is delivered to the reaction core by the transfer RNA molecule (yellow).
  • Silicon 'neurons' may add a new dimension to chips
    Details
    82368
    Silicon 'neurons' may add a new dimension to chips
  • Linux Networx Accelerators Expected to Drive up to 4x Price/Performance
    Details
    76331
  • Complex Concepts That Really Add Up
    Details
    74919
    Complex Concepts That Really Add Up
  • Blue Sky Studios Donates Animation SuperComputer to Wesleyan
    Details
    68912
    Each rack holds 52 Angstrom Microsystem-brand “blades,” with a memory footprint of 12 or 24 gigabytes each. (Photos by Olivia Bartlett Drake)
    Each rack holds 52 Angstrom Microsystem-brand “blades,” with a memory footprint of 12 or 24 gigabytes each. (Photos by Olivia Bartlett Drake)
  • Humanities, HPC connect at NERSC
    Details
    58792
  • TeraGrid ’09 'Call for Participation'
    Details
    55725
  • Turbulence responsible for black holes' balancing act
    Details
    53170
  • Cray Wins $52 Million SuperComputer Contract
    Details
    50887
  • SDSC Researchers Accurately Predict Protein Docking
    Details
    47073
  • FRONTPAGE
  • LATEST
  • POPULAR
  • REGISTER
  • SOCIAL
  • VIDEO
  • SUBSCRIPTION
  • RSS
  • GUIDELINES
  • PRIVACY
  • TOS
  • ABOUT
  • +1 (816) 799-4488
  • editorial@supercomputingonline.com
© 2001 - 2026 SuperComputingOnline.com, LLC. All rights reserved. This material may not be published, broadcast, rewritten or redistributed without permission.
Sign In
  • FRONT PAGE
  • LATEST
    • MEDIA KIT
    • MOST READ
    • RSS FEED
    • ACADEMIA
    • AEROSPACE
    • APPLICATIONS
    • ASTRONOMY
    • AUTOMOTIVE
    • BIG DATA
    • BIOLOGY
    • CHEMISTRY
    • CLIENTS
    • CLOUD
    • DEFENSE
    • DEVELOPER TOOLS
    • EARTH SCIENCES
    • ECONOMICS
    • ENGINEERING
    • ENTERTAINMENT
    • HEALTH
    • INDUSTRY
    • INTERCONNECTS
    • GAMING
    • GOVERNMENT
    • MANUFACTURING
    • MIDDLEWARE
    • MOVIES
    • NETWORKS
    • OIL & GAS
    • PHYSICS
    • PROCESSORS
    • RETAIL
    • SCIENCE
    • STORAGE
    • SYSTEMS
    • VISUALIZATION
  • VIDEOS
    • ADD YOUR VIDEOS
    • MANAGE VIDEOS
  • COMMUNITY
    • TRADE SHOWS
    • SOCIAL NETWORK VIDEOS
    • SURVEYS
    • APPLICATIONS BROWSER
    • CONVERSATION INBOX
    • SOCIAL ADVERTISER
    • GROUPS
    • MARKETPLACE LISTINGS
    • PAGES
    • LEADERBOARD
    • POINTS LISTING
      • BADGES
    • PRIVACY CONFIRM REQUEST
    • PRIVACY CREATE REQUEST

Hey there! We noticed you’re using an ad blocker.