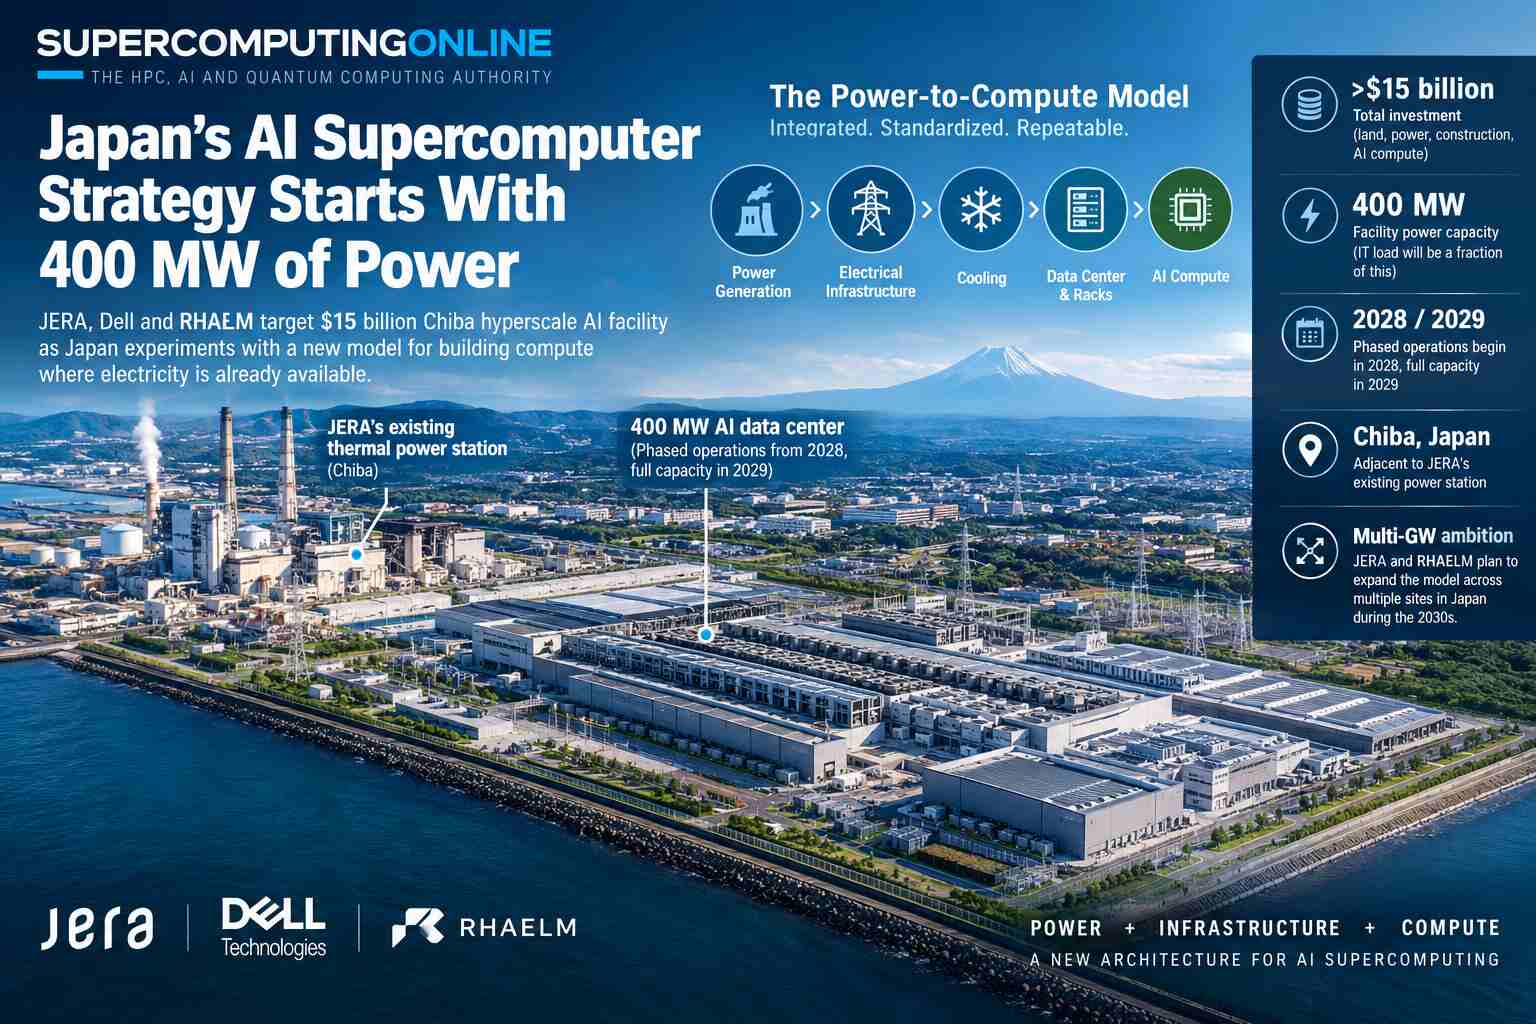
JERA, Dell and RHAELM target $15 billion Chiba hyperscale AI facility as Japan experiments with a new model for building compute where electricity is already available
The next generation of AI supercomputing may not begin with a GPU.
It may begin with a power plant.
In a strategic collaboration, Japan’s primary power generator, JERA, has partnered with Dell Technologies and AI infrastructure developer RHAELM Holdings to pioneer a novel hyperscale computing model. This initiative integrates electricity generation, electrical infrastructure, advanced cooling, data center construction, and rack-scale AI computing into a single, cohesive deployment rather than treating them as fragmented projects.
The model’s inaugural implementation is a planned 400-megawatt AI data center in Chiba, situated adjacent to JERA’s existing thermal power station. This ambitious undertaking represents a total capital commitment exceeding $15 billion, covering land acquisition, power infrastructure, facility development, and AI compute capacity. According to JERA and Reuters, operations are projected to start in phases by 2028, with the facility achieving its full 400-MW capacity by 2029.
For the supercomputing industry, however, the financial scale and construction timeline are secondary to the underlying innovation. The partners are addressing one of the AI era's most critical challenges: rapidly converting raw electrical power into scalable, high-performance computing capacity.
The power bottleneck becomes the computing bottleneck
For decades, supercomputer deployments have generally been treated as technology projects. A facility is built, electrical capacity is secured, cooling systems are installed, networks are provisioned, and compute systems are eventually delivered and integrated.
AI is putting pressure on that sequence.
Modern AI clusters can require enormous amounts of power concentrated into relatively small physical footprints. Thousands of accelerators operating simultaneously create not only a power requirement but also a corresponding cooling, networking, storage and electrical-distribution problem.
As AI systems become larger, the availability of processors is therefore only one part of the equation.
There has to be somewhere to plug them in.
The Chiba project attacks that problem from the opposite direction. Rather than first developing a conventional grid-connected data center and then waiting for sufficient electrical capacity to become available, the partners plan to place the compute infrastructure alongside an existing generation asset.
JERA says the project will operate behind the meter, using power capacity from its operating generation asset. The company argues that this can allow AI computing capacity to come online years earlier than a conventional grid-connected development schedule.
That concept changes the starting point for hyperscale AI construction.
Instead of:
Data center → grid connection → wait for power → compute
the model becomes:
Generation → electrical infrastructure → cooling → compute
The distinction could become increasingly important as AI data-center developers encounter lengthy grid-interconnection queues and constrained transmission capacity.
400 MW is a supercomputing-scale number
The Chiba facility’s 400 MW power capacity provides a useful indication of the scale of infrastructure being contemplated.
It is important, however, to distinguish between facility power capacity and compute power.
A 400-MW data center does not mean 400 MW of GPUs or accelerators.
The site’s electrical envelope must support much more than processors. It encompasses power conversion and distribution, cooling infrastructure, networking, storage, CPUs, memory, accelerator systems, building systems, and other facility loads.
The actual IT load will depend on the final design and power-utilization characteristics of the facility.
Nevertheless, 400 MW represents an enormous potential computing envelope.
At high accelerator densities, the facility could support an extraordinary concentration of AI compute. The precise number of GPUs or other accelerators cannot be calculated from the 400-MW figure alone because it depends on the eventual rack architecture, accelerator selection, networking topology, storage requirements, and facility overhead.
That uncertainty is important.
400 MW is a statement about the infrastructure’s ability to deliver power, not a published specification for the number of processors inside it.
The rack becomes the building block
Dell’s role in the project points toward another important architectural change.
The company will provide standardized, rack-scale AI infrastructure, with JERA describing Dell’s AI Factory as the mechanism for standardizing the compute layer.
That is significant because the rack is becoming an increasingly important unit of AI infrastructure.
Traditional data-center architecture often treated servers as relatively interchangeable building blocks. AI clusters are different. Accelerator systems require carefully engineered relationships among:
- accelerators;
- host CPUs;
- high-bandwidth memory;
- local and parallel storage;
- high-speed fabric;
- power distribution;
- thermal management;
- software;
- orchestration; and
- cluster management.
The result is closer to a supercomputer node architecture multiplied across thousands of systems than to a conventional server farm.
At hyperscale, the physical rack itself becomes a systems-engineering object.
Power delivery, liquid cooling, network topology, and compute density must all be designed around the rack.
Dell’s standardized rack-scale approach is therefore intended to make the compute component repeatable.
RHAELM’s role is to integrate that compute infrastructure with the site, power and data-center construction.
JERA supplies the power and physical location.
The three pieces form the proposed deployment model.
Cooling becomes a first-class HPC problem
Power is only half of the physical equation.
Nearly every watt consumed by an accelerator eventually becomes heat that must be removed.
That means a 400-MW-class AI facility is also a massive thermal-management project.
As accelerator densities increase, traditional air cooling becomes increasingly difficult to apply economically at the highest rack densities. Liquid cooling, whether direct-to-chip, cold-plate or other advanced architectures, can provide substantially greater heat-transfer capability.
JERA’s announcement specifically identifies cooling infrastructure as one of the elements the partners intend to standardize alongside power generation, electrical infrastructure and AI computing.
That detail may ultimately prove more important than it first appears.
A future AI supercomputer is not simply a collection of processors connected by a network.
It is a coupled physical system:
electricity → voltage conversion → compute → heat → liquid cooling → heat rejection
Every stage affects the others.
A higher-density accelerator rack may deliver more AI performance per unit of floor space, but it simultaneously increases electrical and thermal engineering requirements.
The ability to standardize those systems could become one of the keys to shortening deployment times.