NTT DATA’s Munich facility points toward a new model for enterprise computing, but the real test is whether a benchmark survives contact with production
The enterprise AI sector has spent recent years emphasizing the necessity of increased compute capacity. The current challenge, however, lies in ensuring organizations can accurately determine their specific infrastructure requirements. This premise drives the emergence of "AI factories," production-grade environments where enterprises can stress-test workloads, data, and security requirements before committing significant capital to infrastructure.
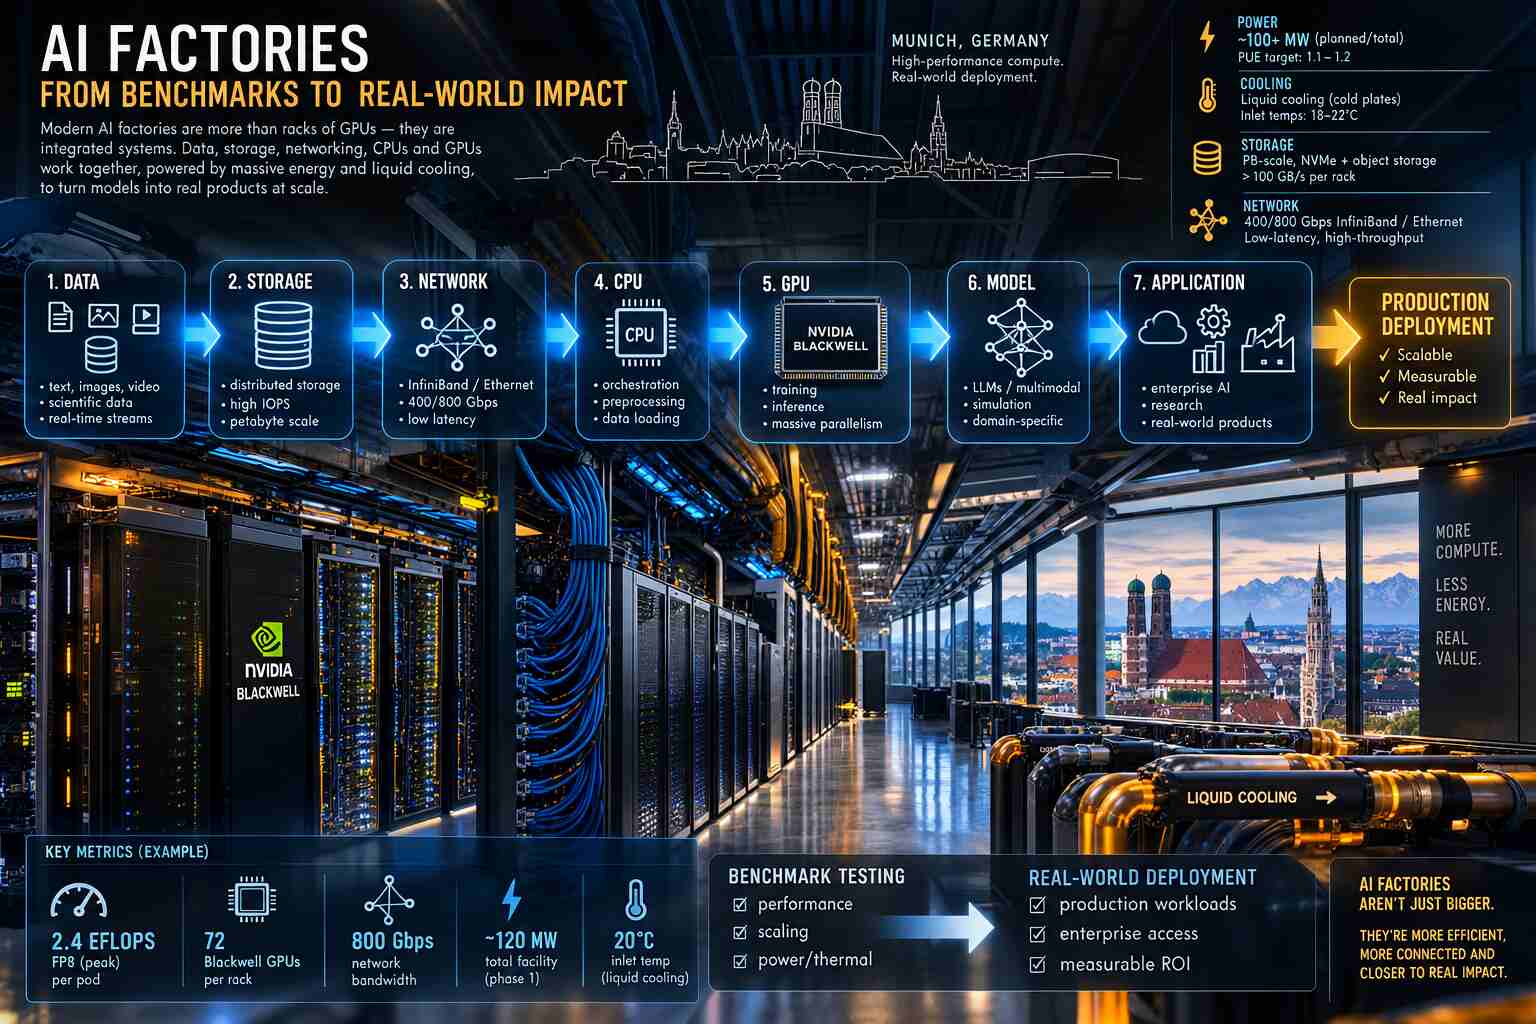
NTT DATA has operationalized this concept with the launch of its AI Factory in Munich, situated within the NTT Global Data Centers’ Munich 2 facility. The site serves as a live proving ground, allowing public and private sector organizations to evaluate AI applications against the infrastructure, governance, and operational realities they will encounter in production. Utilizing a technology stack that includes NVIDIA Blackwell GPUs, Spectrum-X Ethernet networking, and Dell AI-optimized hardware, the facility offers clients actionable benchmark data and architectural guidance. While this approach represents a pragmatic evolution in AI deployment, it warrants a rigorous level of scrutiny beyond standard industry infrastructure announcements.
The end of the AI demo?
The traditional enterprise AI proof of concept has an obvious weakness.
A model works.
A presentation follows.
Everyone nods.
Then somebody tries to deploy it.
Suddenly the GPU cluster is not the problem, or at least not the only problem.
Data has to move. Storage has to keep up. Networks become congested. Models have to be monitored and updated. Security policies have to be enforced. Authentication has to work. Data cannot necessarily cross a national border. Users expect predictable latency. Multiple workloads compete for accelerators. And the expensive GPUs purchased for peak demand spend portions of their lives waiting for data.
The difference between a successful AI demonstration and a successful production system is therefore increasingly becoming an HPC systems problem.
AI factories are an attempt to close that gap.
NTT DATA’s Munich facility explicitly exposes customers to high-performance GPU compute, enterprise storage and high-throughput networking, with visibility into utilization, job queues and performance metrics. Its program is designed to culminate in a benchmark report and architecture recommendation.
That is much closer to the methodology of a supercomputing center than a conventional technology showroom.
But there is a catch.
A benchmark is only as good as the workload
The most important question for an AI factory is not how many Blackwell GPUs it contains.
It is what exactly is being measured.
AI performance is notoriously sensitive to workload characteristics.
Training throughput can depend on model architecture, batch size, precision, optimizer behavior, parallelization strategy, and communication patterns. Inference performance can change dramatically depending on sequence length, concurrency, quantization, batching, and latency requirements.
Then there is the infrastructure beneath the accelerators.
A GPU that spends part of its time waiting for data doesn't deliver its theoretical performance.
A high-performance network that cannot be fed efficiently by storage does not solve the storage problem.
And a massive GPU cluster with poor scheduling efficiency can produce an impressive peak-performance number while delivering disappointing real-world utilization.
This is where AI factories could become genuinely valuable, but also where their claims need to be examined most carefully.
A meaningful validation exercise should measure more than accelerator utilization.
It should examine:
- GPU utilization and duty cycle
- GPU-to-GPU communication efficiency
- network bandwidth and latency
- collective communication performance
- storage throughput and I/O latency
- checkpoint and recovery behavior
- data-ingestion rates
- model-loading times
- training scaling efficiency
- inference latency and throughput
- concurrent workload interference
- scheduler efficiency
- power consumption
- performance per watt
- cost per training run
- cost per inference
- system behavior under sustained load
The difference between peak performance and sustained application performance is where many infrastructure stories become considerably less glamorous.
The supercomputer is no longer just the GPU cluster
The emerging architecture also changes what we mean by a supercomputer.
For decades, HPC engineers thought about systems as tightly integrated combinations of processors, memory, interconnect, storage, and software.
AI is bringing that thinking into the enterprise.
The accelerator is only one component of the system.
The real computational pipeline increasingly looks something like: data → storage → network → CPU → GPU → interconnect → model → inference/training pipeline → application → user
A bottleneck anywhere along that path can determine the performance of the entire system.
NTT DATA itself has acknowledged the networking problem in its broader AI infrastructure analysis, pointing to infrastructure bottlenecks as a significant obstacle to AI ambitions and noting that AI workloads demand increasingly predictable, low-latency data movement.
That observation may ultimately be more important than another announcement about GPU availability.
The AI factory is effectively attempting to test the entire computational organism, rather than merely the processor at its center.
Blackwell is impressive. That isn’t the same as proving the architecture.
NVIDIA Blackwell hardware will naturally attract attention.
But customers should resist the temptation to interpret a successful Blackwell demonstration as proof that every Blackwell deployment will produce comparable results.
The surrounding system matters.
Networking topology matters.
Storage architecture matters.
Software versions matter.
Compiler and library optimization matters.
Workload characteristics matter.
Power and cooling constraints matter.
And, perhaps most importantly, utilization matters.
Buying a large accelerator cluster because a benchmark demonstrates exceptional throughput at 100% utilization is not necessarily rational if the production workload spends much of its time at 20% utilization.
This is a familiar HPC problem wearing a new AI label.
A supercomputer’s theoretical capability can be enormous while its application-level efficiency is considerably lower.
AI factories therefore have an opportunity to bring something valuable to enterprise buyers: measurement before procurement.
But the industry should be careful not to replace one form of marketing with another.
Sovereign AI makes the experiment more complicated
Munich also highlights another reason AI factories are emerging: sovereignty.
European organizations increasingly have to consider where their data resides, who controls the infrastructure, what jurisdictions apply to the data, and how AI systems fit within regulatory requirements.
NTT DATA specifically positions the Munich facility around private and sovereign AI architectures, data residency and governance. The company says customers can evaluate those requirements alongside performance and infrastructure considerations.
That is significant because sovereignty itself has a performance cost.
An organization may discover that the fastest possible architecture is not the architecture it is legally or operationally permitted to deploy.
Data may have to remain inside a particular jurisdiction.
Certain services may be unavailable.
Some workloads may need to run on dedicated infrastructure.
Security controls may add latency or complexity.
The result is a more realistic definition of performance: “The best AI system is not necessarily the fastest system. It is the fastest system an organization can actually operate, govern, secure, and afford.”
That is a much more interesting engineering problem.
The AI factory could become an enterprise supercomputing center
There is a historical parallel worth watching.
HPC centers have long provided researchers with access to sophisticated computing systems they could not economically own themselves. They also provide expertise in application optimization, benchmarking, scheduling, and system architecture.
AI factories could evolve into a commercial version of that model.
Instead of asking an enterprise to purchase a massive infrastructure stack based on a vendor presentation, the organization could first bring its workload to an AI factory.
Run it.
Profile it.
Stress it.
Measure it.
Optimize it.
Then decide what infrastructure is actually required.
That could fundamentally change the procurement process.
Rather than: “How many GPUs do we need?” the question becomes: “What system configuration delivers the required application performance at an acceptable cost, power envelope, security level, and utilization rate?”
That is a far better question.
But there is still a giant unanswered question: production
The biggest weakness in the AI factory concept is also the hardest problem to solve.
A controlled validation environment is still controlled.
Enterprise production environments are messy.
They contain legacy databases, unpredictable user demand, inconsistent networks, changing data pipelines, security policies, software dependencies, and workloads nobody remembered to mention during the architecture meeting.
A benchmark performed on a carefully prepared workload may therefore tell an organization what its AI system can do under those conditions.
It does not necessarily tell the organization what will happen six months later.
That means AI factories will ultimately have to demonstrate something beyond benchmark numbers.
They will need to establish repeatability.
Can the workload be reproduced?
Can performance be maintained as data volumes grow?
What happens when multiple models compete for the same infrastructure?
How does performance degrade under network congestion?
What happens when GPUs fail?
How quickly can workloads recover?
What does the system cost at 30%, 50%, and 80% utilization?
And perhaps the most important question: Does the resulting infrastructure actually produce enough business value to justify its power, hardware, software, and operational costs?
Those are the questions that should determine whether an AI architecture survives.
The power problem doesn’t disappear in an AI factory
The power problem doesn’t disappear in an AI factory
There is another uncomfortable reality.
AI factories don’t eliminate the physical constraints of AI computing.
They concentrate them.
The industry is already confronting the enormous electrical requirements of large-scale AI infrastructure. Adding more GPU clusters, high-performance networking, and storage simply increases the importance of power delivery, cooling, and data-center efficiency.
A validation environment can tell a customer how fast an application runs.
It should also tell the customer how much electricity it consumed to run it.
That metric needs to become standard.
Performance per watt, performance per dollar, and ultimately useful AI work per unit of energy may prove more meaningful than theoretical accelerator performance.
Otherwise, enterprises risk optimizing an AI system that is technically magnificent and economically irrational.
From AI theater to computational evidence
The NTT DATA Munich initiative warrants serious consideration, not simply as another facility in a saturated market, but because it advances the industry toward a principle long recognized by high-performance computing (HPC) engineers: the true capabilities of a system remain unknown until the application is executed within it.
The AI factory model represents a potential shift from theoretical architecture diagrams to empirically verified computational performance. However, this promise merits a measured, skeptical outlook. Should these facilities merely serve as sophisticated showrooms for vendor-optimized hardware under ideal conditions, their industry impact will be negligible. Conversely, if they function as genuinely independent, rigorously measured validation environments, they could become a cornerstone of the enterprise AI infrastructure ecosystem.
Ultimately, the success of this model hinges upon the depth and integrity of its metrics. Peak FLOPS, GPU counts, and polished demonstrations are insufficient. The definitive benchmark will be the facility’s ability to accurately forecast system behavior once an application transitions from the controlled testing environment into the unpredictable realities of production.